char-fork/llama.cpp
git clone https://git.t4t.associates/char-fork/llama.cpp
a278dcef0
char/aliceai-t5-moe
Contributors
The project differentiates between 3 levels of contributors:
- Contributors: people who have contributed before (no special privileges)
- Collaborators (Triage): people with significant contributions, who may be responsible for some parts of the code, and are expected to maintain and review contributions for the code they own
- Maintainers: responsible for reviewing and merging PRs, after approval from the code owners
AI Usage Policy
[!IMPORTANT]
AI-generated code is allowed. You are 100% responsible for every line, however it was produced.
Undisclosed AI usage may result in your account being permanently banned from contributing to the project.
Detailed information regarding permissible and restricted uses of AI can be found in the AGENTS.md file.
If AI is used to generate any portion of the code, contributors must adhere to the following requirements:
- Explicitly disclose the manner in which AI was employed.
- Check for an existing PR addressing the same change; if one exists, comment there to work with its author instead of opening a duplicate.
- Perform a comprehensive manual review prior to submitting the pull request.
- Be prepared to explain every line of code they submitted when asked about it by a maintainer.
- It is strictly prohibited to use AI to write your posts for you (bug reports, feature requests, pull request descriptions, Github discussions, responding to humans, ...).
For more info, please refer to the AGENTS.md file.
Pull requests (for contributors & collaborators)
Before you start
- Search for existing discussions and PRs first - duplicates will likely be closed without questions.
- Features must begin with an issue, not a PR - let interest accumulate before writing code; niche features may only land as an example/tool, or on a private fork.
- Bug-fix PRs must include a reproducible issue and a regression test that fails before your change and passes after. Fixes without a test may be closed without review.
- New CLI or public API additions carry a higher bar than internal changes - justify why an existing mechanism doesn't suffice.
- Meeting all of the above still doesn't guarantee a merge - see Pull requests (for maintainers).
- If you are a new contributor
- Limit your open PRs to 1
- Do not submit trivial fixes (e.g. typos, formatting changes)
Preparing your PR
- llama.cpp uses the ggml tensor library for model evaluation. If you are unfamiliar with ggml, consider taking a look at the examples in the ggml repository. simple shows the bare minimum for using ggml. gpt-2 has minimal implementations for language model inference using GPT-2. mnist demonstrates how to train and evaluate a simple image classifier
- Test your changes:
- Execute the full CI locally on your machine before publishing
- Verify that the perplexity and the performance are not affected negatively by your changes (use
llama-perplexityandllama-bench) - If you modified the
ggmlsource, run thetest-backend-opstool to check whether different backend implementations of theggmloperators produce consistent results (this requires access to at least two differentggmlbackends) - If you modified a
ggmloperator or added a new one, add the corresponding test cases totest-backend-ops
- Create separate PRs for each feature or fix:
- Avoid combining unrelated changes in a single PR
- When adding support for a new model or feature, focus on CPU support only in the initial PR unless you have a good reason not to. Add support for other backends like CUDA in follow-up PRs
- In particular, adding new data types (extension of the
ggml_typeenum) carries with it a disproportionate maintenance burden. As such, to add a new quantization type you will need to meet the following additional criteria at minimum:- convert a small model to GGUF using the new type and upload it to HuggingFace
- provide perplexity comparisons to FP16/BF16 (whichever is the native precision) as well as to types of similar size
- provide KL divergence data calculated vs. the FP16/BF16 (whichever is the native precision) version for both the new type as well as types of similar size
- provide performance data for the new type in comparison to types of similar size on pure CPU
- Consider allowing write access to your branch for faster reviews, as reviewers can push commits directly
After submitting your PR
- Expect requests for modifications to ensure the code meets llama.cpp's standards for quality and long-term maintainability
- Maintainers will rely on your insights and approval when making a final decision to approve and merge a PR
- If your PR becomes stale, rebase it on top of latest
masterto get maintainers attention - Consider adding yourself to CODEOWNERS to indicate your availability for fixing related issues and reviewing related PRs
Pull requests (for maintainers)
- Squash-merge PRs
- Use the following format for the squashed commit title:
<module> : <commit title> (#<issue_number>). For example:utils : fix typo in utils.py (#1234) - Optionally pick a
<module>from here: https://github.com/ggml-org/llama.cpp/wiki/Modules - Let other maintainers merge their own PRs
- When merging a PR, make sure you have a good understanding of the changes
- If a PR does not warrant a new release, add
[no release]in the squashed commit to spare CI resources - Be mindful of maintenance: most of the work going into a feature happens after the PR is merged. If the PR author is not committed to contribute long-term, someone else needs to take responsibility (you)
- Add the "merge ready" label to a PR to indicate when a PR can be fast-merged without waiting for 2 independent reviews. (more info)
- Wait for CI results before merging
Maintainers reserve the right to decline review or close pull requests for any reason, without any questions, particularly under any of the following conditions:
- The proposed change is already mentioned in the roadmap or an existing issue, and it has been assigned to someone.
- The pull request duplicates an existing one.
- The contributor fails to adhere to this contributing guide or the AI policy.
- The change doesn't fit the existing architecture, or is too complex to justify its benefit.
Coding guidelines
-
Avoid adding third-party dependencies, extra files, extra headers, etc.
-
Always consider cross-compatibility with other operating systems and architectures
-
Avoid fancy-looking modern STL constructs, use basic
forloops, avoid templates, keep it simple -
Vertical alignment makes things more readable and easier to batch edit
-
Clean-up any trailing whitespaces, use 4 spaces for indentation, brackets on the same line,
void * ptr,int & a -
Use sized integer types such as
int32_tin the public API, e.g.size_tmay also be appropriate for allocation sizes or byte offsets -
Declare structs with
struct foo {}instead oftypedef struct foo {} foo- In C++ code omit optional
structandenumkeyword whenever they are not necessary
// OK llama_context * ctx ;const llama_rope_type rope_type ;// not OK struct llama_context * ctx ;const enum llama_rope_type rope_type ;(NOTE: this guideline is yet to be applied to the
llama.cppcodebase. New code should follow this guideline.) - In C++ code omit optional
-
Try to follow the existing patterns in the code (indentation, spaces, etc.). In case of doubt use
clang-format(from clang-tools v15+) to format the added code -
For anything not covered in the current guidelines, refer to the C++ Core Guidelines
-
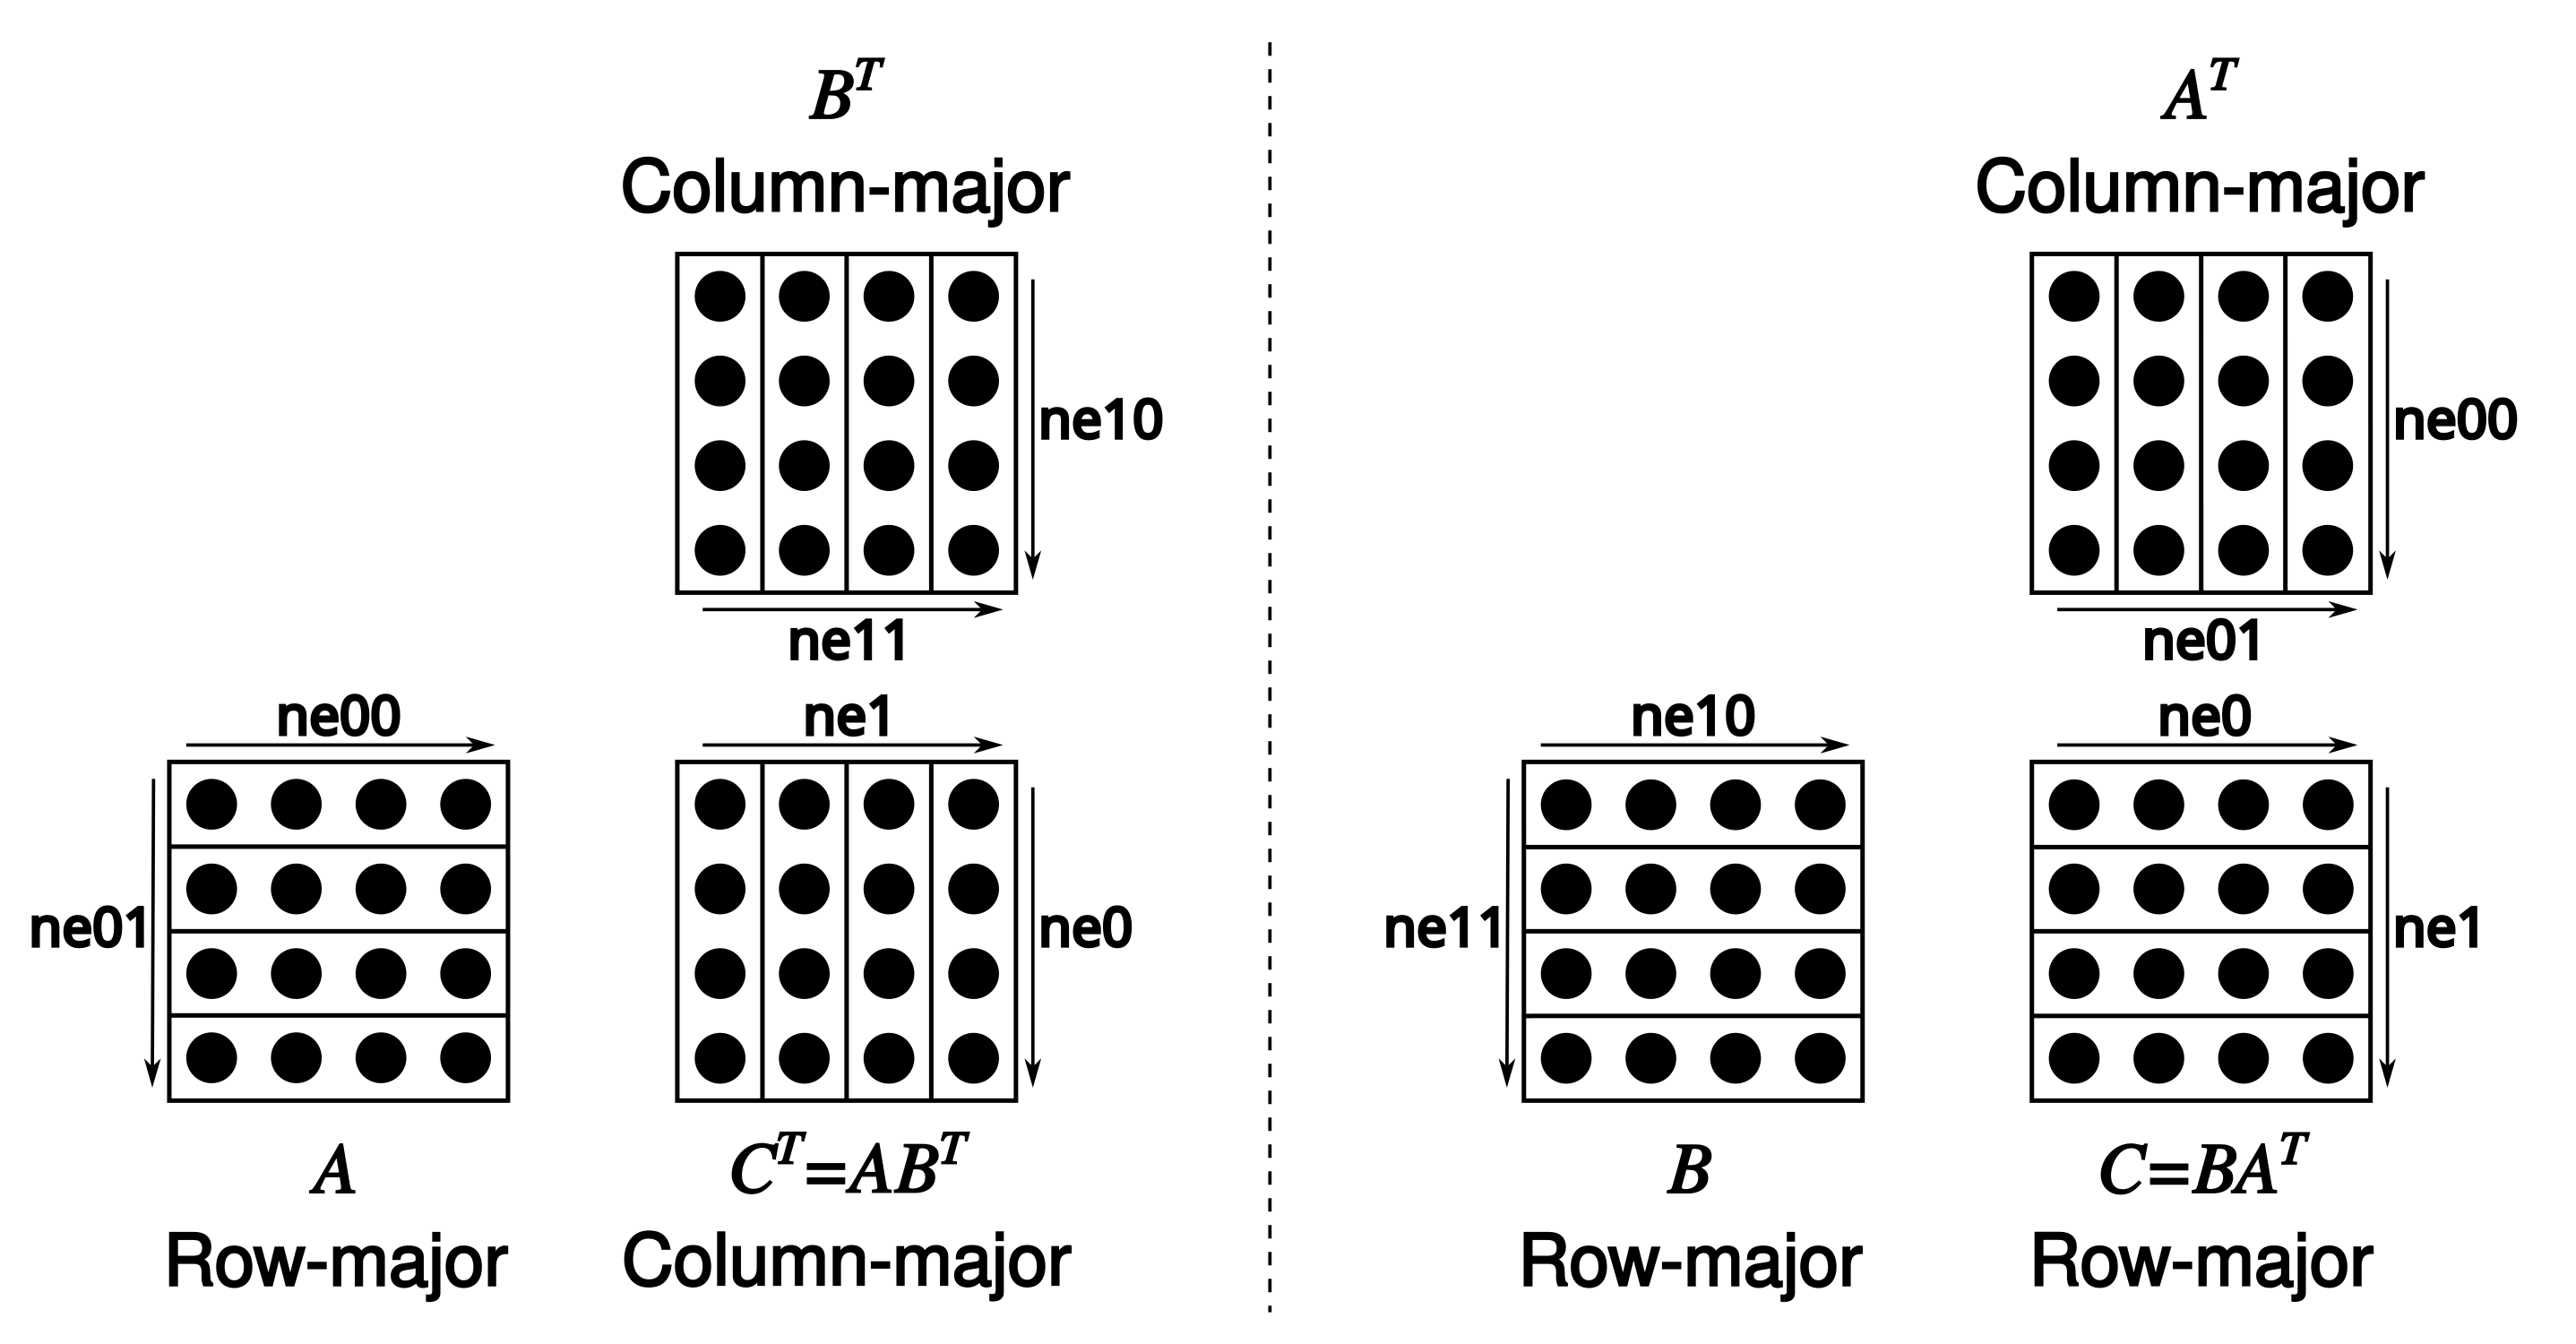
Tensors store data in row-major order. We refer to dimension 0 as columns, 1 as rows, 2 as matrices
-
Matrix multiplication is unconventional:
C = ggml_mul_mat(ctx, A, B)means $C^T = A B^T \Leftrightarrow C = B A^T.$
Naming guidelines
-
Use
snake_casefor function, variable and type names -
Naming usually optimizes for longest common prefix (see https://github.com/ggml-org/ggml/pull/302#discussion_r1243240963)
// not OK int small_number ;int big_number ;// OK int number_small ;int number_big ; -
Enum values are always in upper case and prefixed with the enum name
enum llama_vocab_type {LLAMA_VOCAB_TYPE_NONE = 0 ,LLAMA_VOCAB_TYPE_SPM = 1 ,LLAMA_VOCAB_TYPE_BPE = 2 ,LLAMA_VOCAB_TYPE_WPM = 3 ,LLAMA_VOCAB_TYPE_UGM = 4 ,LLAMA_VOCAB_TYPE_RWKV = 5 , }; -
The general naming pattern is
<class>_<method>, with<method>being<action>_<noun>llama_model_init ();// class: "llama_model", method: "init" llama_sampler_chain_remove ();// class: "llama_sampler_chain", method: "remove" llama_sampler_get_seed ();// class: "llama_sampler", method: "get_seed" llama_set_embeddings ();// class: "llama_context", method: "set_embeddings" llama_n_threads ();// class: "llama_context", method: "n_threads" llama_adapter_lora_free ();// class: "llama_adapter_lora", method: "free" - The
get<action>can be omitted - The
<noun>can be omitted if not necessary - The
_contextsuffix of the<class>is optional. Use it to disambiguate symbols when needed - Use
init/freefor constructor/destructor<action>
- The
-
Use the
_tsuffix when a type is supposed to be opaque to the user - it's not relevant to them if it is a struct or anything elsetypedef struct llama_context * llama_context_t ;enum llama_pooling_type llama_pooling_type (const llama_context_t ctx );(NOTE: this guideline is yet to be applied to the
llama.cppcodebase. New code should follow this guideline) -
C/C++ filenames are all lowercase with dashes. Headers use the
.hextension. Source files use the.cor.cppextension -
Python filenames are all lowercase with underscores
-
(TODO: abbreviations usage)
Preprocessor directives
-
(TODO: add guidelines with examples and apply them to the codebase)
#ifdef FOO
#endif // FOO
Code maintenance
-
Existing code should have designated collaborators and/or maintainers specified in the CODEOWNERS file responsible for:
- Reviewing and merging related PRs
- Fixing related bugs
- Providing developer guidance/support
-
When adding or modifying a large piece of code:
- If you are a collaborator, make sure to add yourself to CODEOWNERS to indicate your availability for reviewing related PRs
- If you are a contributor, find an existing collaborator who is willing to review and maintain your code long-term
- Provide the necessary CI workflow (and hardware) to test your changes (see ci/README.md)
-
New code should follow the guidelines (coding, naming, etc.) outlined in this document. Exceptions are allowed in isolated, backend-specific parts of the code that do not interface directly with the
ggmlinterfaces. (NOTE: for legacy reasons, existing code is not required to follow this guideline) -
For changes in server, please make sure to refer to the server development documentation
Documentation
- Documentation is a community effort
- When you need to look into the source code to figure out how to use an API consider adding a short summary to the header file for future reference
- When you notice incorrect or outdated documentation, please update it
Resources
The Github issues, PRs and discussions contain a lot of information that can be useful to get familiar with the codebase. For convenience, some of the more important information is referenced from Github projects:
https://github.com/ggml-org/llama.cpp/projects
1# Contributors 2 3The project differentiates between 3 levels of contributors: 4 5- Contributors: people who have contributed before (no special privileges) 6- Collaborators (Triage): people with significant contributions, who may be responsible for some parts of the code, and are expected to maintain and review contributions for the code they own 7- Maintainers: responsible for reviewing and merging PRs, after approval from the code owners 8 9# AI Usage Policy 10 11> [!IMPORTANT] 12> 13> AI-generated code is allowed. You are 100% responsible for every line, however it was produced. 14> 15> Undisclosed AI usage may result in your account being permanently banned from contributing to the project. 16> 17> Detailed information regarding permissible and restricted uses of AI can be found in the [AGENTS.md](AGENTS.md) file. 18 19If AI is used to generate any portion of the code, contributors must adhere to the following requirements: 20 211. Explicitly disclose the manner in which AI was employed. 222. Check for an existing PR addressing the same change; if one exists, comment there to work with its author instead of opening a duplicate. 233. Perform a comprehensive manual review prior to submitting the pull request. 244. Be prepared to explain every line of code they submitted when asked about it by a maintainer. 255. It is strictly prohibited to use AI to write your posts for you (bug reports, feature requests, pull request descriptions, Github discussions, responding to humans, ...). 26 27For more info, please refer to the [AGENTS.md](AGENTS.md) file. 28 29# Pull requests (for contributors & collaborators) 30 31### Before you start 32 33- Search for existing discussions and PRs first - duplicates will likely be closed without questions. 34- Features must begin with an issue, not a PR - let interest accumulate before writing code; niche features may only land as an example/tool, or on a private fork. 35- Bug-fix PRs must include a reproducible issue and a regression test that fails before your change and passes after. Fixes without a test may be closed without review. 36- New CLI or public API additions carry a **higher bar** than internal changes - justify why an existing mechanism doesn't suffice. 37- Meeting all of the above still doesn't guarantee a merge - see [Pull requests (for maintainers)](#pull-requests-for-maintainers). 38- If you are a new contributor 39- Limit your open PRs to 1 40- Do not submit trivial fixes (e.g. typos, formatting changes) 41 42### Preparing your PR 43 44- llama.cpp uses the ggml tensor library for model evaluation. If you are unfamiliar with ggml, consider taking a look at the [examples in the ggml repository](https://github.com/ggml-org/ggml/tree/master/examples/). [simple](https://github.com/ggml-org/ggml/tree/master/examples/simple) shows the bare minimum for using ggml. [gpt-2](https://github.com/ggml-org/ggml/tree/master/examples/gpt-2) has minimal implementations for language model inference using GPT-2. [mnist](https://github.com/ggml-org/ggml/tree/master/examples/mnist) demonstrates how to train and evaluate a simple image classifier 45- Test your changes: 46- Execute [the full CI locally on your machine](ci/README.md) before publishing 47- Verify that the perplexity and the performance are not affected negatively by your changes (use `llama-perplexity` and `llama-bench`) 48- If you modified the `ggml` source, run the `test-backend-ops` tool to check whether different backend implementations of the `ggml` operators produce consistent results (this requires access to at least two different `ggml` backends) 49- If you modified a `ggml` operator or added a new one, add the corresponding test cases to `test-backend-ops` 50- Create separate PRs for each feature or fix: 51- Avoid combining unrelated changes in a single PR 52- When adding support for a new model or feature, focus on **CPU support only** in the initial PR unless you have a good reason not to. Add support for other backends like CUDA in follow-up PRs 53- In particular, adding new data types (extension of the `ggml_type` enum) carries with it a disproportionate maintenance burden. As such, to add a new quantization type you will need to meet the following *additional* criteria *at minimum*: 54- convert a small model to GGUF using the new type and upload it to HuggingFace 55- provide [perplexity](https://github.com/ggml-org/llama.cpp/tree/master/tools/perplexity) comparisons to FP16/BF16 (whichever is the native precision) as well as to types of similar size 56- provide KL divergence data calculated vs. the FP16/BF16 (whichever is the native precision) version for both the new type as well as types of similar size 57- provide [performance data](https://github.com/ggml-org/llama.cpp/tree/master/tools/llama-bench) for the new type in comparison to types of similar size on pure CPU 58- Consider allowing write access to your branch for faster reviews, as reviewers can push commits directly 59 60### After submitting your PR 61 62- Expect requests for modifications to ensure the code meets llama.cpp's standards for quality and long-term maintainability 63- Maintainers will rely on your insights and approval when making a final decision to approve and merge a PR 64- If your PR becomes stale, rebase it on top of latest `master` to get maintainers attention 65- Consider adding yourself to [CODEOWNERS](CODEOWNERS) to indicate your availability for fixing related issues and reviewing related PRs 66 67# Pull requests (for maintainers) 68 69- Squash-merge PRs 70- Use the following format for the squashed commit title: `<module> : <commit title> (#<issue_number>)`. For example: `utils : fix typo in utils.py (#1234)` 71- Optionally pick a `<module>` from here: https://github.com/ggml-org/llama.cpp/wiki/Modules 72- Let other maintainers merge their own PRs 73- When merging a PR, make sure you have a good understanding of the changes 74- If a PR does not warrant a new release, add `[no release]` in the squashed commit to spare CI resources 75- Be mindful of maintenance: most of the work going into a feature happens after the PR is merged. If the PR author is not committed to contribute long-term, someone else needs to take responsibility (you) 76- Add the ["merge ready"](https://github.com/ggml-org/llama.cpp/pulls?q=is%3Apr+is%3Aopen+draft%3Ano+sort%3Aupdated-desc+label%3A%22merge+ready%22+) label to a PR to indicate when a PR can be fast-merged without waiting for 2 independent reviews. [(more info)](https://github.com/ggml-org/llama.cpp/pull/26178) 77- Wait for CI results before merging 78 79Maintainers reserve the right to decline review or close pull requests for any reason, without any questions, particularly under any of the following conditions: 80- The proposed change is already mentioned in the roadmap or an existing issue, and it has been assigned to someone. 81- The pull request duplicates an existing one. 82- The contributor fails to adhere to this contributing guide or the AI policy. 83- The change doesn't fit the existing architecture, or is too complex to justify its benefit. 84 85# Coding guidelines 86 87- Avoid adding third-party dependencies, extra files, extra headers, etc. 88- Always consider cross-compatibility with other operating systems and architectures 89- Avoid fancy-looking modern STL constructs, use basic `for` loops, avoid templates, keep it simple 90- Vertical alignment makes things more readable and easier to batch edit 91- Clean-up any trailing whitespaces, use 4 spaces for indentation, brackets on the same line, `void * ptr`, `int & a` 92- Use sized integer types such as `int32_t` in the public API, e.g. `size_t` may also be appropriate for allocation sizes or byte offsets 93- Declare structs with `struct foo {}` instead of `typedef struct foo {} foo` 94- In C++ code omit optional `struct` and `enum` keyword whenever they are not necessary 95```cpp 96// OK 97llama_context * ctx ; 98const llama_rope_type rope_type ; 99 100// not OK 101struct llama_context * ctx ; 102const enum llama_rope_type rope_type ; 103``` 104 105_(NOTE: this guideline is yet to be applied to the `llama.cpp` codebase. New code should follow this guideline.)_ 106 107- Try to follow the existing patterns in the code (indentation, spaces, etc.). In case of doubt use `clang-format` (from clang-tools v15+) to format the added code 108- For anything not covered in the current guidelines, refer to the [C++ Core Guidelines](https://isocpp.github.io/CppCoreGuidelines/CppCoreGuidelines) 109- Tensors store data in row-major order. We refer to dimension 0 as columns, 1 as rows, 2 as matrices 110- Matrix multiplication is unconventional: [`C = ggml_mul_mat(ctx, A, B)`](https://github.com/ggml-org/llama.cpp/blob/880e352277fc017df4d5794f0c21c44e1eae2b84/ggml.h#L1058-L1064) means $C^T = A B^T \Leftrightarrow C = B A^T.$ 111 112 113 114# Naming guidelines 115 116- Use `snake_case` for function, variable and type names 117- Naming usually optimizes for longest common prefix (see https://github.com/ggml-org/ggml/pull/302#discussion_r1243240963) 118 119```cpp 120// not OK 121int small_number ; 122int big_number ; 123 124// OK 125int number_small ; 126int number_big ; 127``` 128 129- Enum values are always in upper case and prefixed with the enum name 130 131```cpp 132enum llama_vocab_type { 133LLAMA_VOCAB_TYPE_NONE = 0 , 134LLAMA_VOCAB_TYPE_SPM = 1 , 135LLAMA_VOCAB_TYPE_BPE = 2 , 136LLAMA_VOCAB_TYPE_WPM = 3 , 137LLAMA_VOCAB_TYPE_UGM = 4 , 138LLAMA_VOCAB_TYPE_RWKV = 5 , 139}; 140``` 141 142- The general naming pattern is `<class>_<method>`, with `<method>` being `<action>_<noun>` 143 144```cpp 145llama_model_init (); // class: "llama_model", method: "init" 146llama_sampler_chain_remove (); // class: "llama_sampler_chain", method: "remove" 147llama_sampler_get_seed (); // class: "llama_sampler", method: "get_seed" 148llama_set_embeddings (); // class: "llama_context", method: "set_embeddings" 149llama_n_threads (); // class: "llama_context", method: "n_threads" 150llama_adapter_lora_free (); // class: "llama_adapter_lora", method: "free" 151``` 152 153- The `get` `<action>` can be omitted 154- The `<noun>` can be omitted if not necessary 155- The `_context` suffix of the `<class>` is optional. Use it to disambiguate symbols when needed 156- Use `init`/`free` for constructor/destructor `<action>` 157 158- Use the `_t` suffix when a type is supposed to be opaque to the user - it's not relevant to them if it is a struct or anything else 159 160```cpp 161typedef struct llama_context * llama_context_t ; 162 163enum llama_pooling_type llama_pooling_type ( const llama_context_t ctx ); 164``` 165 166_(NOTE: this guideline is yet to be applied to the `llama.cpp` codebase. New code should follow this guideline)_ 167 168- C/C++ filenames are all lowercase with dashes. Headers use the `.h` extension. Source files use the `.c` or `.cpp` extension 169- Python filenames are all lowercase with underscores 170 171- _(TODO: abbreviations usage)_ 172 173# Preprocessor directives 174 175- _(TODO: add guidelines with examples and apply them to the codebase)_ 176 177```cpp 178#ifdef FOO 179#endif // FOO 180``` 181 182# Code maintenance 183 184- Existing code should have designated collaborators and/or maintainers specified in the [CODEOWNERS](CODEOWNERS) file responsible for: 185- Reviewing and merging related PRs 186- Fixing related bugs 187- Providing developer guidance/support 188 189- When adding or modifying a large piece of code: 190- If you are a collaborator, make sure to add yourself to [CODEOWNERS](CODEOWNERS) to indicate your availability for reviewing related PRs 191- If you are a contributor, find an existing collaborator who is willing to review and maintain your code long-term 192- Provide the necessary CI workflow (and hardware) to test your changes (see [ci/README.md](https://github.com/ggml-org/llama.cpp/tree/master/ci)) 193 194- New code should follow the guidelines (coding, naming, etc.) outlined in this document. Exceptions are allowed in isolated, backend-specific parts of the code that do not interface directly with the `ggml` interfaces. 195_(NOTE: for legacy reasons, existing code is not required to follow this guideline)_ 196 197- For changes in server, please make sure to refer to the [server development documentation](./tools/server/README-dev.md) 198 199# Documentation 200 201- Documentation is a community effort 202- When you need to look into the source code to figure out how to use an API consider adding a short summary to the header file for future reference 203- When you notice incorrect or outdated documentation, please update it 204 205# Resources 206 207The Github issues, PRs and discussions contain a lot of information that can be useful to get familiar with the codebase. For convenience, some of the more important information is referenced from Github projects: 208 209https://github.com/ggml-org/llama.cpp/projects